Velorix Velorix

How to Choose an NVIDIA GPU Server Manufacturer

Time:2026-11-13 Author:Henry
0%

Choosing an nvidia gpu server manufacturer is not just a matter of comparing GPU models. It means checking whether the complete system fits your workloads, facility, and support needs. Jensen Huang, NVIDIA’s founder and CEO, has called AI “the most powerful technology force of our time.” That broader observation helps explain why GPU server decisions now affect research teams, cloud providers, and growing businesses. It does not, by itself, identify the right supplier.

Look beyond the product page. Ask how the manufacturer validates GPU, CPU, memory, and networking configurations under sustained loads. Check power and cooling requirements against your rack: a dense server can be impressive on paper and impractical in a warm, space-limited room. Request clear warranty terms, realistic delivery estimates, and access to engineers who understand NVIDIA platforms. Small details matter. A vague answer about replacement parts can become a costly delay later.

This guide outlines practical ways to assess technical expertise, build quality, scalability, service, and total cost. It also considers how to compare vendors without treating a low quote as proof of value. No checklist removes every risk. A configuration that suits one team may be excessive for another, and vendor claims still need verification. That is worth remembering. The aim is not to find a flawless manufacturer, but to choose one that explains its trade-offs and can support the system after installation.
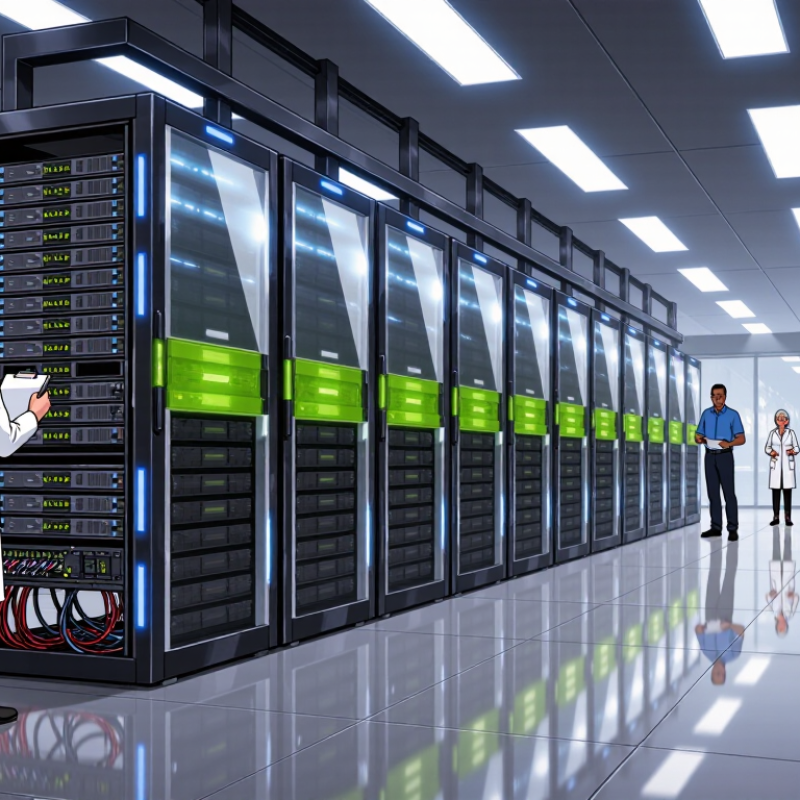
How to Choose an NVIDIA GPU Server Manufacturer

Define Your Workload and NVIDIA GPU Server Requirements

Start with the workload, not the card count. Training a large model, serving inference, and rendering stress a server differently. Training needs fast GPU-to-GPU links and enough memory for model weights, activations, and checkpoints. Inference may favor predictable latency, while scientific jobs may need high-precision compute or large memory. Measure batch size, sequence length, concurrent users, and response-time targets using real workload traces. Small details matter.

Stanford HAI’s 2024 AI Index reports that training compute for notable AI models has doubled about every five months. A server sized only for today’s peak may quickly feel cramped. Translate expected growth into a 12–24-month capacity plan, then verify power, cooling, rack depth, and network bandwidth with the manufacturer.

Ask for tested GPU counts per node, memory capacity, interconnect topology, storage throughput, and sustained power draw. Peak figures can mislead. Real workloads run hot.

Tips: Bring a representative workload, not just a synthetic benchmark. Request a pilot using your software stack, thermal limits, and failure-recovery process. Record job completion time, inference throughput, and energy use. Leave room for an awkward constraint: your facility’s cooling may become the bottleneck, not the GPU.

Compare GPU Server Platforms, Configurations, and Scalability

A GPU server platform should be judged by its workload, not its headline accelerator count. For training, compare GPU interconnect bandwidth, topology, and sustained power delivery. For inference, memory capacity and latency under simultaneous requests may matter more. Ask for a topology diagram, not only a specification sheet. Small details matter.

Compare configurations with equal care. Check accelerator count, CPU lanes, system memory, local NVMe capacity, and network speed. Then confirm the chassis fits your rack and can handle the heat load. Request benchmark results using your own model or a similar workload. A short test can reveal throttling that a brief demonstration misses.

Scalability means more than adding servers later. Check whether the platform supports the networking, cooling, and management tools your planned cluster needs. Ask about expansion costs, delivery times, and validated configurations. Leave spare rack power and cooling capacity; estimates are often optimistic. I would still question one assumption: future workloads may need more memory, not more GPUs. Plan for both where practical.

Evaluate the Manufacturer’s Engineering and Validation Capabilities

A manufacturer’s engineering claims should be testable, not just persuasive. Ask for thermal maps, power-budget calculations, and validation records for the exact server configuration you plan to buy. A chassis that works in a cool lab may throttle when every accelerator runs at full load. Look for sustained-load tests that record temperatures, clock speeds, power draw, and error rates—not a brief peak-performance demonstration. Small details matter. Check whether the test included your intended workload, firmware settings, and rack airflow.

Power and reliability deserve equal scrutiny. The IEA’s Electricity 2024 report estimates that data centres, AI, and cryptocurrency used about 460 TWh in 2022; demand in its high-growth scenario could exceed 1,000 TWh by 2026. That makes realistic power and cooling validation essential. Uptime Institute’s Global Data Center Survey 2024 found that 54% of respondents had experienced an outage in the previous three years. This is not a GPU-server-specific measure, but it highlights the cost of weak operational testing. Request documented burn-in procedures, failure logs, and acceptance criteria, then ask how engineers reproduce faults and verify fixes. I would still question any test report that omits ambient temperature or workload duration; those gaps can make a clean result less useful than it looks.

How to Choose an NVIDIA GPU Server Manufacturer - Evaluate the Manufacturer’s Engineering and Validation Capabilities
Capability Evidence to Request Questions to Ask Strong Indicators Potential Warning Signs
System architecture and configuration engineering Configuration drawings, bill of materials, supported GPU and CPU combinations, memory population rules, and documented expansion limits. How are component compatibility and configuration changes reviewed? Are supported configurations documented and version-controlled? Clear configuration records; engineering review of component changes; documented limits for GPU count, memory, storage, and expansion. Undocumented substitutions, unclear configuration limits, or reliance on verbal assurances about compatibility.
Power delivery and redundancy Power budgets for supported configurations, power-supply specifications, redundancy behavior, and system power or fault-test procedures. How is peak system demand calculated? What happens during a power-supply failure or loss of an input feed? Power budgets account for the installed configuration; supported redundancy modes and failure behavior are documented and tested. Power capacity is described only by a headline rating, without configuration-specific calculations or failure-mode information.
Thermal and airflow engineering Thermal design documentation, fan-control behavior, inlet-temperature limits, airflow requirements, and test results for representative configurations. Under what inlet conditions and workloads are thermal tests performed? How are airflow restrictions and fan failures handled? Thermal limits and installation requirements are explicit; testing covers sustained workloads and relevant operating conditions. Cooling claims lack test conditions, or the system’s airflow and ambient-temperature requirements are not specified.
High-speed interconnect and signal integrity Design and validation records for supported PCIe links, risers, cables, connectors, and other high-speed interfaces. How are link operation and error rates checked across supported configurations? Are changes to risers, cables, or board layouts revalidated? Interface components are controlled by configuration; link training and error checks are included in validation procedures. Interconnect parts are substituted without documented compatibility review or system-level testing.
Mechanical design and serviceability Chassis and rack drawings, component-clearance checks, installation instructions, and procedures for replacing serviceable parts. Can key components be serviced without disturbing unrelated assemblies? Are rack depth, weight, and handling requirements documented? Service steps and physical constraints are documented; fit and access are checked for the intended deployment environment. Unclear installation requirements, obstructed service access, or no defined handling procedure for heavy equipment.
Firmware and platform integration Firmware inventory, release notes, update procedures, configuration records, and a process for tracking security and compatibility changes. How are firmware versions qualified as a set? How are updates deployed, verified, and recovered if an update fails? Version compatibility is documented; updates have defined validation and recovery procedures; release notes identify relevant changes. Firmware versions are not tracked, update methods are unclear, or changes are applied without a regression check.
System-level validation Test plans and sample reports covering startup, sustained operation, workload testing, hardware monitoring, and fault handling. Which tests are run on each configuration? What conditions constitute a failure, and how are defects documented and retested? Tests have stated acceptance criteria; failures are recorded and corrected; representative production configurations are tested. Validation is described as a basic power-on check, with no documented workload coverage or defect-closure process.
Manufacturing quality and traceability Assembly and inspection procedures, production test records, serial-level traceability, and processes for managing nonconforming parts. Can delivered units be traced to their configuration and test results? How are build errors and supplier changes controlled? Build records link unit identity, configuration, and test status; nonconformances are documented and dispositioned. Limited unit-level records, informal assembly checks, or no clear process for controlling component substitutions.
Safety and regulatory readiness Applicable safety and electromagnetic-compatibility documentation for the intended markets, plus records identifying the tested product configuration. Which requirements apply to the system and deployment market? Do documents cover the final system configuration rather than only individual parts? Applicable requirements and documentation are identified; evidence corresponds to the shipped system and intended market. Compliance claims are unsupported, do not identify the applicable configuration, or confuse component documentation with system-level evidence.
Lifecycle engineering and support Product change-notification process, spare-parts policy, supported-component list, and procedures for handling end-of-life parts. How are component changes assessed for compatibility? What support and spare-parts coverage is available for the expected service period? Changes are communicated and reviewed; replacement parts are qualified; support scope and escalation paths are clearly stated. Unannounced substitutions, no defined change-control process, or unclear availability of compatible replacement parts.

Assess Supply Chain Reliability, Technical Support, and Service

A GPU server is only as dependable as the parts and people behind it. Ask manufacturers how they track processors, memory, power supplies, and cooling components from order to shipment. Request realistic lead times, not best-case estimates, and ask what happens when a component is delayed. A clear answer should include rules for substitute parts and written approval for changes. That matters.

Test technical support before purchase. Ask who handles firmware, driver, and thermal issues, and whether engineers can review your workload and rack limits. Check support hours, response targets, escalation steps, and access to remote diagnostics. Send a sample configuration and ask for feedback on airflow, power draw, and network needs. Vague replies are a warning.

Service quality shows up after installation. Confirm warranty coverage, replacement-part availability, repair locations, and how failed systems are serviced. Ask whether spare parts are kept near your site and whether the supplier provides a maintenance plan. Compare service commitments with your uptime needs, not just the lowest quote. Some details may still change as supply conditions shift; that is worth admitting. Put assumptions, exclusions, and update intervals in writing, then review them before deployment.

Compare Compliance, Total Cost of Ownership, and Vendor Fit

When choosing an NVIDIA GPU server manufacturer, compare documented capabilities, not broad assurances. Ask for compliance records that apply to the exact server configuration, including its components and production site. Check document dates and scope. A certificate may not cover every model. Request clear answers about hardware traceability, data handling, and how configuration changes are recorded. These details help your technical and procurement teams assess risk with evidence.

Total cost of ownership extends beyond the purchase price. Estimate power use under your expected workload, cooling needs, rack space, support fees, and likely downtime. Measure before committing. Ask vendors to explain their test conditions; benchmark results can shift with workload, software, and temperature. Compare warranty terms, response targets, replacement-part availability, and delivery estimates over your intended service period. A low initial quote can become expensive if support is slow or capacity is hard to expand.

Tips: Share a representative workload and request a written configuration, power estimate, and support plan. Check compatibility with your existing network, storage, and monitoring tools. Then speak with the engineers who will operate the system. A polished proposal is useful, but operational fit matters more. I would still leave room for uncertainty: real workloads rarely match a perfect test.

FAQS

How should I choose a GPU server configuration?

Start with your workload, not the number of cards. Training, inference, and rendering place different demands on memory, links, and response times.

What workload details should I measure?

Record batch size, sequence length, concurrent users, and response-time targets. Use real workload traces when possible. Small details matter.

How far ahead should I plan capacity?

Estimate needs for the next 12–24 months. Model growth may make today’s peak capacity feel cramped sooner than expected.

Which server specifications should I verify?

Check GPU count, memory, interconnect layout, storage throughput, and sustained power draw. Peak figures can mislead.

How can I test a server before buying?

Run a pilot with your software, thermal limits, and recovery process. Measure job time, inference throughput, and energy use.

What facility limits could affect deployment?

Confirm cooling, power, rack depth, and network bandwidth. A hot rack can become the bottleneck, even with capable GPUs.

What should I ask about component supply?

Request realistic delivery dates and clear rules for substitute parts. Require written approval before components change.

How can I evaluate technical support and service?

Ask who handles firmware, driver, and thermal issues. Check response targets, replacement-part availability, repair locations, and warranty coverage. Vague replies deserve a second look.

What should be documented before deployment?

Put assumptions, exclusions, service terms, and update intervals in writing. Supply conditions can shift; our estimates may still be imperfect.

Conclusion

Choosing an nvidia gpu server manufacturer starts with a clear understanding of your workload, including the applications you plan to run, expected performance, memory needs, and future growth. Use these requirements to compare server platforms, GPU configurations, networking, storage, and options for scaling capacity. A suitable system should support your current use cases while allowing room to expand without unnecessary complexity or expense.

Look beyond specifications to assess the manufacturer’s engineering, testing, and validation processes, as well as its ability to provide dependable components, technical guidance, and responsive service. Consider delivery reliability, warranty and support arrangements, relevant compliance needs, and the total cost of ownership, including power, maintenance, and upgrades. By weighing these factors against your operational priorities and budget, you can select a manufacturing partner and server solution that fit your organization over the long term.
Henry

Henry

Henry is a dedicated marketing professional with a profound expertise in the company's offerings. With years of experience in the industry, he possesses an impressive understanding of the market dynamics and consumer behaviors that drive success. Henry is committed to sharing his insights through......